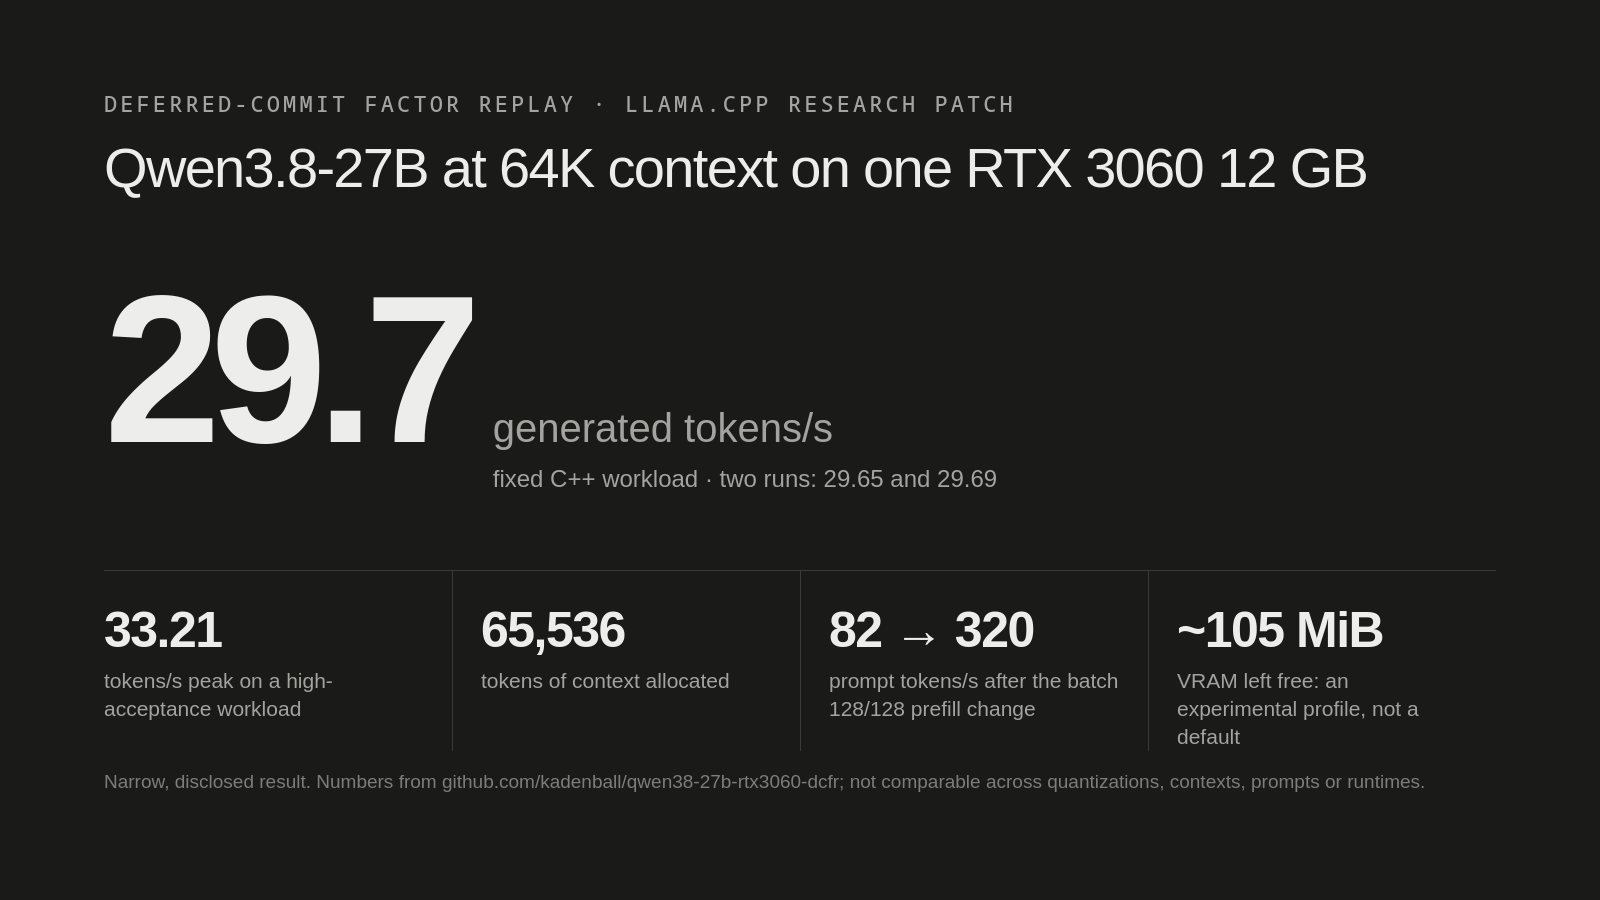
This moot is about one narrow result: Qwen3.8-27B generating at about 29.7 tokens per second with a 65,536-token context allocated on a single RTX 3060 12 GB, using an experimental llama.cpp patch.
The optimization is called Deferred-Commit Factor Replay. Speculative decoding normally keeps extra copies of the model’s recurrent state in case guesses are rejected. The patch removes hundreds of MiB of those copies and spends the saved VRAM on model weights.
It is a disclosed, narrow result, not a claim that every prompt runs this fast. The final profile leaves about 105 MiB of VRAM free. The patch, exact settings, caveats and raw measurements are in the repository.
What I’d like from you
If you have a 12 GB card, try to reproduce it and post your numbers, whatever they are: GPU, driver, prompt, accepted and drafted tokens, tokens per second. A report of where it fails is as useful as a confirmation.
September 18 update: Q4 at 32K with cached chat
A separate IQ4_XS interactive profile now allocates 32,768 tokens on the RTX 3060 12 GB: 60% more capacity than the previous 20,480-token Q4 preset. Two short runs per coding task measured a mean 16.06 tok/s for Rust and 14.30 tok/s for C++. These are Q4 results, separate from the original IQ3 figures above.
The main improvement is avoiding repeated prompt ingestion. A synthetic harness follow-up reused 25,950 input tokens, processed only 25 new tokens, and completed 102 output tokens in 12.1 seconds. Prompt processing took 2.02 seconds; decode at roughly 26K occupied context was 11.09 tok/s. An earlier uncached follow-up took 159.1 seconds, but history and output lengths differ, so this is not a matched 13× speedup claim. Cold prefill still takes time.
The profile uses MTP-3 with ordinary recurrent-state backups, not D-CFR. The tested deeper-replay path clears cross-request prompt state for correctness; that safeguard was not removed. Additional CPU offload accommodates ordinary backups. About 698 MiB of device memory remained after short tests, not a peak-memory or OOM guarantee.
Local harness fixes also prevent excessively small output allowances and unproductive tiny-prefix compaction. Thirty regression tests passed. No full-window quality claim is made. The additional runtime optimizations and optional version-pinned DSH corrections are now published in a separate Q4 source release. The historical IQ3 build remains unchanged.
Full report, settings and limitations · Machine-readable measurements
Run the published Q4 32K profile
Complete installation and run guide
Measured hardware: RTX 3060 12 GB, Intel i5-12400, 16 GB RAM, Linux x86-64. The CPU path requires AVX2; the attention optimization is guarded for SM 8.6. Allow 30 GB free disk for model/source/build, plus toolchain space. The tested toolchain is CUDA 13.3 and GCC/G++ 15; the guide lists dependencies and compatibility limits. Other GPUs and Windows/WSL are not validated by this release.
The repository now includes the runtime patches, pinned upstream source/archive checksum, exact model revision and checksum, resumable model download, standalone launch script, synthetic benchmark fixtures, CPU and attention-memory checks, and a chat-cache/marker verification script. No separate draft-model download is required. The Q4 file is Bartowski IQ4_XS, not Q4_K_M or an uncensored fine-tune.
After cloning the repository and installing the documented prerequisites:
```sh
bash scripts/build-q4.sh
bash scripts/download-q4.sh
bash scripts/serve-q4.sh
```
Connect an OpenAI-compatible client to http://127.0.0.1:8080/v1, model qwen38-q4-32k, context 32768. The guide includes DeepSeek Harness and Zterm connection settings, reasoning settings, optional hash-pinned DSH fixes, verification commands, troubleshooting and rollback. The server is loopback-only; authenticated remote access must be provided by the client/harness.
Fresh-build verification passed: 7,680 bit-exact CPU cases, 680 CPU graph checks, 80 attention allocation contracts and 30 DSH regressions. The short Rust/C++ fixtures measured 15.83/14.36 tok/s means. The separate chat smoke test recalled its marker in both replies and reused 2,514 tokens, processing 17 new tokens in a 2.60-second follow-up. This is not a repeat of the earlier 26K occupied-context test or a new speed record.